I Broke Down AI Rank API Results. Here’s What They Can Prove
Abstract evidence paths. The article text defines what each returned result can support.
An AI Rank API result can show whether a specified domain appears in the returned citations for a particular query and label. It cannot, on its own, prove a brand was recommended or describe what every user would see for that question. Keep the answer, citation and missing-result evidence before you turn any of it into a visibility chart.
I founded Serpent API, so my view of its fields is affiliated. The October 5, 2026 source review for this article checked the public AI Rank API contract and pricing. No live cross-product test was run for this article; the code and numerical examples are illustrative. The labels here are the Serpent AI Rank engines named in the public contract.
Start with a question and the claim you intend to make
Choose a question a buyer would actually ask, the domain you want to track, and a market. The documented GET /api/ai/rank request accepts q (or keyword), optional domain, comma-separated engines, prompt_type, country and language. Its labels are claude, chatgpt, gemini and perplexity. Keep the question, domain, selected labels and market fixed when you compare dates.
If your report needs a screenshot or a record of what a particular person saw on screen, capture it directly and record the account, location, date and screen. Use the Serpent API workflow when the question is narrower: what evidence did this named API result return under these saved parameters?
| Returned field | What it supports | What it does not support |
|---|---|---|
response_text | Reviewing the answer text from that API result | A claim about all users or interfaces. |
citations[] | Specific links, titles and citation context | A recommendation or endorsement. |
target_found | Domain or subdomain present in that result’s citations | That the brand was positively discussed. |
aggregate.visibility_score | A Serpent summary for a fixed engine set | Comparing unlike subsets or market share. |
Save the evidence before you calculate a rate
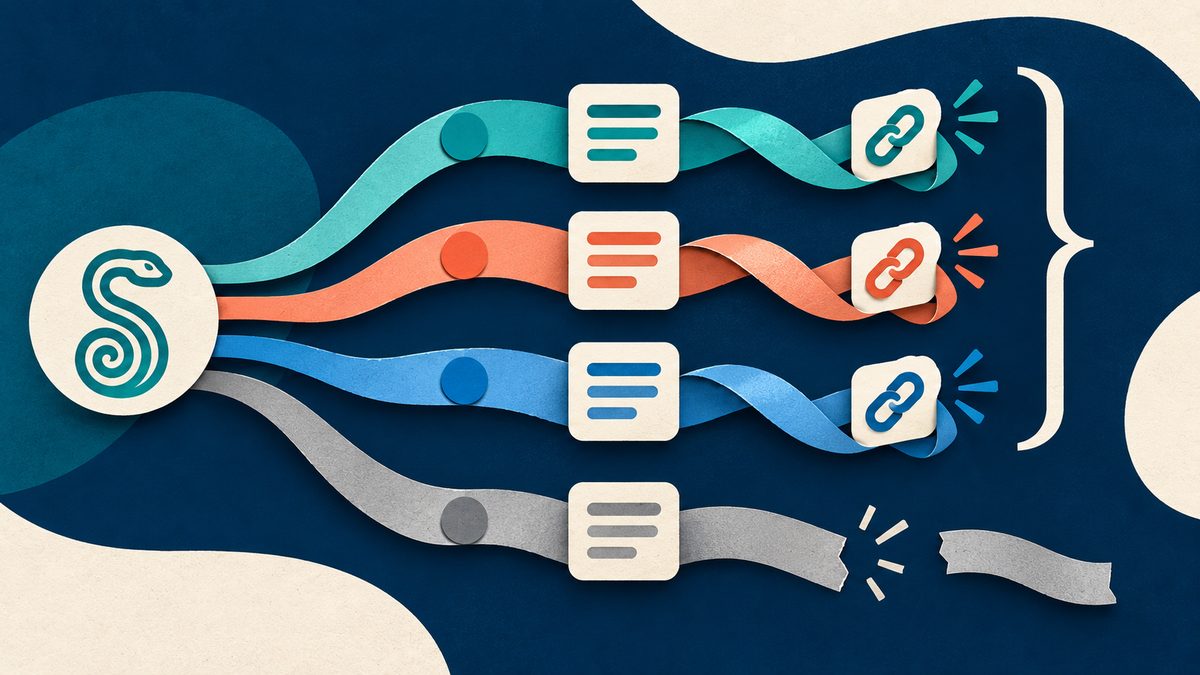
The illustrative Python example requests all four documented labels for one question, retains each returned answer and citation, and records a distinct state when a label is unusable. A domain match is only a citation finding. Store any raw response under your normal access controls so a reviewer can inspect the answer later.
Use Python 3, install requests with python -m pip install requests, and set SERPENT_API_KEY. This is an example built from the public contract, not a transcript of a run performed for this article.
import json, os
from datetime import datetime, timezone
import requests

params = {"q": "best project planning tools for a small team",
          "domain": "example.com", "engines": "claude,chatgpt,gemini,perplexity",
          "prompt_type": "standard", "country": "us", "language": "en"}
r = requests.get("https://apiserpent.com/api/ai/rank", params=params,
    headers={"X-API-Key": os.environ["SERPENT_API_KEY"]}, timeout=120)
r.raise_for_status()
data = r.json()
if data.get("success") is not True: raise ValueError("No usable AI Rank answer")
results = data.get("results")
if not isinstance(results, dict): raise ValueError("Missing per-label results")
ledger = []
for label in params["engines"].split(","):
    item = results.get(label)
    if not isinstance(item, dict):
        ledger.append({"label": label, "state": "missing"})
        continue
    answer, citations = item.get("response_text"), item.get("citations")
    if not isinstance(answer, str) or not answer.strip() or not isinstance(citations, list):
        ledger.append({"label": label, "state": "unavailable_or_unusable"})
        continue
    ledger.append({"label": label, "state": "completed",
       "target_found": item.get("target_found"),
       "target_position": item.get("target_position"),
       "target_match_type": item.get("target_match_type"),
       "target_matched_domain": item.get("target_matched_domain"),
       "answer": answer,
       "citations": [{"position": c.get("position"), "url": c.get("url"),
                      "title": c.get("title"), "domain": c.get("domain"),
                      "url_normalized": c.get("url_normalized"),
                      "cited_text": c.get("cited_text")}
                     for c in citations if isinstance(c, dict)]})
completed = sum(row["state"] == "completed" for row in ledger)
print(json.dumps({"observed_at": datetime.now(timezone.utc).isoformat(),
                  "run_id": data.get("run_id"), "query": params["q"],
                  "domain": params["domain"], "planned_labels": len(ledger),
                  "completed_labels": completed, "labels": ledger,
                  "score_for_comparison": ((data.get("aggregate") or {}).get("visibility_score") if completed == len(ledger) else None)}, indent=2))
Illustrative ledger row: {"label":"gemini","state":"completed","target_found":false,"target_position":null,"answer":"Example answer text","citations":[]}. It shows a completed response with no target citation; it is not a real answer. Save the run_id and observation time for traceability. The example keeps the aggregate score out of date-to-date comparison if even one requested label was unusable.
Read the answer, not just the match flag
- Citation: inspect the returned URL, normalized URL, domain, position and cited text. A linked page may support a different point in the answer. Open it before reporting the citation as evidence for your brand.
- Mention: read the returned
response_textin context. A brand name can appear without a domain citation, while a domain can be cited without the brand name in the prose. - Recommendation: let a reviewer mark the exact passage and its qualification, such as “good for small teams.” A neutral comparison or negative warning is not a positive recommendation merely because the brand appears.
Which evidence route fits the question?
| Route | Strongest use | Limit to state in the report |
|---|---|---|
| Manual review of the relevant app | Direct evidence of what a reviewer saw in that app, on a recorded date and account | Slow to repeat; the observation may vary by session and person. |
| Official Google AI feature guidance | Understanding Google’s stated Search feature and reporting rules | Documentation explains the product; it is not a saved answer for your query. |
| Serpent AI Rank API | Repeatable request parameters and returned answer, citation and domain-match fields | It describes one saved Serpent AI Rank result for the parameters you sent. A person still needs to judge context. |
I would use manual app review when the deliverable promises a screenshot or a record of what a named person saw. For a scheduled citation ledger, the API fields make collection easier to repeat, provided the report names Serpent as its source and includes missing responses. Neither route turns one answer into a population-wide visibility estimate.
For a budget illustration, ten fixed queries weekly for four weeks require 40 combined calls if each call selects multiple labels. The Serpent Default price listed on October 5, 2026 was $40 per 1,000 combined calls, or $1.60 for that schedule; a single-label call was listed at $20 per 1,000. This is arithmetic from published prices, not a paid usage test. Storage, reviewer time and any other workflow costs are additional. Keep the same label set across dates because the published score scale depends on the selection.
Define the denominator before calculating a brand rate
A useful question panel has a reason each question belongs: discovery, comparison, purchase or support. Freeze the wording and target domain for a reporting period. Save one row per planned question and selected Serpent label, with an explicit completed, missing or unreviewed state. For a citation rate, divide cited completed responses by all completed, usable responses; disclose the planned count and the number that did not complete. Do not count an unavailable result as a completed result with zero citations.
| Finding | Evidence to retain | Reader-facing wording |
|---|---|---|
| Target domain in citations | Returned URL, label, query and cited answer context | “The Serpent response cited this domain.” |
| Brand name in answer only | Answer passage and reviewer decision | “The returned answer mentioned the brand.” |
| Positive recommendation | Full answer context and human review | “In this answer, the brand was recommended for …” |
| Missing or incomplete label | Response state and requested parameters | “No finding for this label in this run.” |
Suppose a fictional report planned 40 question-label responses: 35 completed and 8 of those cited the target. Its rate is 8/35, about 23%, with 5 unmeasured. Those numbers are an example, not campaign measurements. A “score of zero” would conceal the missing five. When you change the question panel, country or selected labels, start a new series or show both definitions; apparent movement may come from the design change.
Write a claim the evidence can carry
Record the question, date, parameters, completed count and exact citation evidence. A defensible statement is: “For this question and market, the completed Serpent AI Rank response under the specified label cited our domain.” If you reviewed the answer text, report a mention or recommendation as a separate human-coded finding with its passage. One run does not measure general market share or future answers.
The citation review workflow covers checking a returned link, while the AI search visibility metrics guide covers broader reporting choices. See the AI Rank API overview for the current public field list.
Try a small evidence log
Save the same question and label set on repeat runs, with each answer and citation beside the summary.
Get an API keyFAQ
Does target_found mean the brand was recommended?
No. It reports whether the requested domain or subdomain appears in that Serpent response’s citations. Read response_text and cited_text to evaluate what the answer actually says.
Can I compare visibility_score across different engine subsets?
No. The score is scaled to the selected engine set. Keep the same labels and parameters when comparing runs, and keep the underlying citation evidence.
What does visibility_score null mean?
The public contract says the score is null when no domain was sent. A completed run with a domain and no citations may return 0. These are different states.
What do the claude, chatgpt, gemini and perplexity labels mean?
They are the four Serpent AI Rank engines you can select with the engines parameter. Each result reflects one query, one set of parameters and one moment, so keep the labels, parameters and date with every finding; one result does not measure every answer every user might see.